How to Fix Bing Crawl Anomalies Caused by Parameter URLs
Last updated: October 13, 2026
Key Takeaways
- Bing uses links, canonicals, sitemaps, and server responses to choose crawl targets.
- Make Bing see one preferred URL per content set and stop generating junk variants.
- Remove useless parameter URLs from site architecture; use canonical signals only when crawl access still matters.
- Parameter URLs already indexed? Consolidate them rather than only preventing new ones.
Quick Answer: In most cases, fixing Bing crawl anomalies caused by parameter URLs takes 3 steps: clean internal links, set the right canonical, and stop generating low-value variants.
Bing crawling the same page again and again with different query strings usually means those parameter URLs still look like separate pages worth visiting. Tighten the canonicals, cut URL generation at the source, and give Bing a clearer read on which version matters. To fix Bing crawl anomalies caused by parameter URLs, start with the URL pattern, then the template, then the sitemap.
Why Bing Starts Treating Parameter URLs as Separate Crawl Targets
?sort=, ?page=, ?color=, and session-style parameters can look harmless, but Bing often treats them like distinct crawl targets when the signals are muddy. It follows links, canonicals, sitemaps, and server responses; if those do not line up, the variants spread fast. Microsoft’s Bing Webmaster Guidelines stress clear crawl paths, and Bing Webmaster Tools documentation covers URL inspection and indexing signals.
First, check whether the parameterized URLs return a unique HTML page, a near-duplicate, or the same content with tiny changes. That distinction changes everything. A product page with ?color=red that changes the visible product may be a real page type, though it still deserves careful handling and, when in doubt, a professional SEO review. A page that exists only because of a tracking parameter is usually a cleanup job. A page that contains filtered inventory may need selective indexing rules, not a blanket block. Google’s canonical documentation and Bing’s parameter-handling guidance both support that approach.
Here is the practical rule: if the parameter does not create content that a searcher would reasonably want indexed, then the URL should not act like a standalone page. When Bing can discover it through internal links, XML sitemaps, or external links, you need to make the preferred URL obvious. On larger sites, this is the kind of crawl issue that often warrants advice from a technical SEO professional.
| Situation | Best Path | Why Other Options Fail |
|---|---|---|
Tracking params like utm_, gclid, fbclid |
Normalize, canonicalize to the clean URL, and strip from internal links | Robots.txt alone does not remove already discovered URLs from crawl patterns |
Faceted navigation like ?brand= or ?price= |
Allow only the combinations that deserve indexing; canonical the rest | Noindex on every variant can waste crawl if Bing must still fetch them |
Pagination like ?page=2 |
Keep crawlable if the series matters, but canonical each page to itself | Canonicaling all pages to page 1 can hide deeper content |
Sort/order params like ?sort=price_asc |
Block from internal linking and canonical to the base view | These almost never deserve separate index entries |
| Session IDs or duplicate IDs | Remove at the application layer and set cookies instead | Blocking after the fact does not stop URL creation |
Quick check: if the parameter changes only tracking or presentation, you want cleanup and consolidation; if it changes indexable content, you need selective control, not a blanket ban.
What Actually Fixes Bing Crawl Anomalies?
The fix is simple in theory and a little annoying in practice: make Bing see one preferred URL for each content set, then stop emitting junk variants in the first place. A canonical helps, but it cannot do all the work if the same page is still reachable through 10 parameter strings. On many sites, Bing crawl anomalies caused by parameter URLs do not disappear until the CMS or template logic changes.
A working sequence usually looks like this:
- List the parameter patterns Bing is crawling in Bing Webmaster Tools under URL Inspection, Crawl Control, and the Index Explorer if it is available on your account.
- Group parameters by function: tracking, sorting, pagination, filtering, internal search, session, or language.
- Decide which groups should be indexable, which should be canonicalized, and which should be blocked at generation time.
- Update templates so internal links use clean URLs by default. This is the biggest win on most sites.
- Set canonical tags so parameter URLs point to the preferred clean URL or to the self-referential canonical when the parameter version is intentionally indexable.
- Remove parameter variants from XML sitemaps unless the variant is the only version you want indexed.
- Use 301 redirects when the parameter URL should consolidate into a single clean URL for users. Do not redirect useful filter pages blindly.
- Verify the HTTP status, canonical target, and rendered content with Bing’s URL Inspection and a crawl tool such as Screaming Frog or Sitebulb.
The trade-off is plain: clamp down harder with redirects and robots.txt, and crawl waste drops; push too far, and you may hide pages that should stay visible. That is why I would not make robots.txt the default answer. Bing cannot see a blocked page’s canonical tag if you hide it from crawl entirely.
A useful standard here is one content set, one preferred URL, one canonical signal. That is the whole job, really. Bing is not a special case that likes messy architecture; it rewards clearer structure. The Bing Webmaster Guidelines and the Google Search Central canonical docs both point in that direction.
Quick check: if Bing is crawling dozens of versions of the same path, your fix should start in the CMS or link generation layer, not in robots.txt.
How do I stop Bing from crawling parameter URLs without breaking useful pages?
You stop Bing from crawling useless parameter URLs by removing them from your site architecture and using canonical signals only where crawl is still needed. If the page is genuinely useless to users, then noindex or redirect may be right. If the page is useful but duplicated, then canonicalization is safer. For Bing crawl anomalies caused by parameter URLs, this is usually the most practical split.
This is the decision tree I would use:
- If the parameter is pure tracking such as `utm_source`, `utm_medium`, `gclid`, or `fbclid`, strip it from internal links and keep the clean URL in canonicals and sitemaps.
- If the parameter is sorting or display-only such as `?sort=popular` or `?view=grid`, prevent those variants from being linked internally. They should not be index targets.
- If the parameter changes page identity such as a color or size filter that genuinely changes the product set, decide whether that variant deserves indexing. If yes, give it a self-canonical and a stable internal link pattern. If no, canonical it to the base category.
- If the parameter creates thin internal search results such as `?q=shoes`, keep it out of the index. Internal search pages often generate endless low-value crawl paths.
- If the parameter is session-based, remove it at the application layer. Cookies are usually better than visible session IDs in URLs.
Two common mistakes cause most Bing crawl anomalies. One is hiding parameter URLs in robots.txt while leaving the links in place; Bing can still find them elsewhere, so the crawl pattern stays messy. The other is canonicalizing everything to the home page. Clean on paper, disastrous in practice.
A better pattern is to decide per parameter family:
utm_*,gclid,fbclid: never index, never link internally, normalize everywhere.- Pagination: crawlable if useful, self-canonical on each page.
- Facets: selective, based on whether search demand and content depth justify them.
- Sort and session parameters: remove at source.
Google’s and Bing’s webmaster documentation both emphasize consistent canonical and crawl signals; Bing’s own support pages on URL normalization and parameter handling are worth reading if you are sorting a large site. If you want a broader SEO reference, the IETF’s URI standards are the technical backdrop for why query strings create alternate URL identities.
Quick check: if the URL exists only because of a parameter, ask whether a human would bookmark it. If the answer is no, it usually should not be a crawl target.
What if the parameter URLs are already indexed?
If the parameter URLs are already in Bing’s index, then your job is to consolidate, not just prevent future damage. The good news is that indexed duplicates usually drop once Bing sees stronger, stable signals. The bad news is that this can take multiple recrawls, so you need a plan that is consistent for 4 to 8 weeks, not a one-day fix.
Use this path when the bad URLs are already visible in search:
- Keep the parameter URL live for now unless it is harmful. A dead URL with no redirect creates more uncertainty than a live duplicate with a clear canonical.
- Set the canonical on the parameter URL to the preferred clean URL, or to itself if the variant is intentionally indexable.
- Make sure the preferred clean URL returns a 200 status and self-canonical tags.
- Remove the parameterized versions from XML sitemaps and internal links.
- If the URL should never exist, 301 redirect it to the clean version. Use 410 only when you are certain the page is gone and should vanish, but do not rely on that for routine parameter cleanup.
- Request inspection for the clean URL in Bing Webmaster Tools and monitor whether Bing keeps choosing the correct canonical.
- Recheck server logs or crawl exports after a few weeks to see whether Bingbot still requests the junk variants.
The main trade-off here is speed versus stability. A hard redirect can solve the user-facing problem faster, but if you redirect too broadly you can flatten useful faceted pages into one undifferentiated category. A canonical gives Bing a preference rather than an order. That is slower, but safer when the page family is nuanced.
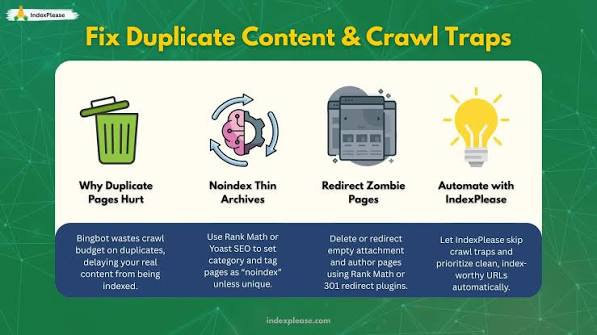
I would not use “noindex, follow” as a catch-all without checking whether Bing still needs to crawl those pages to see the canonical or internal links. A noindex page can still burn crawl budget if your site architecture keeps feeding it.
Quick check: if bad parameter URLs are already ranking or appearing in Bing, focus on canonical consolidation plus source cleanup, not just blocking.
The 3 Conditions That Change Everything
If one of these three conditions is true, then the standard fix changes, and a blanket rule will hurt you.
The first condition is crawl volume. If Bingbot is hitting thousands of parameter combinations on a large catalog site, then crawl waste matters more than minor edge-case indexing. In that case, I would prioritize link pruning, sitemap cleanup, and selective blocking of low-value facet combinations. A site with 50,000 SKUs has less patience for waste than a 200-page brochure site.
The second condition is content uniqueness. If parameter URLs materially change the page’s information — for example, a filter combination that reveals a distinct set of products, articles, or listings — then a self-canonical may be right. Do not force everything to the base page just because the URL contains a question mark. That mistake can erase useful landing pages.
The third condition is server behavior. If the parameter URL returns the same HTML as the clean URL, or if the app rewrites multiple variants server-side without changing the visible content, then Bing sees duplication. In that case, fixing the URL generation layer usually beats every on-page tweak. Canonicals can help, but they are not a substitute for stable architecture.
Here is the practical split I use:
- If the parameter is low-value and high-volume, remove it from internal links and block its creation.
- If the parameter is useful but duplicative, canonicalize it and keep crawl access.
- If the parameter is actually a distinct page, give it its own clean, stable pattern instead of letting query strings do the work.
That last point is where many generic articles go wrong. They assume every parameter URL is bad. Some are. Some are the only way your inventory, search, or filter system exposes relevant content. The right answer is not “kill all parameters.” It is to separate tracking noise from content-bearing URLs, and if you are unsure, consult a technical SEO professional. Bing’s URL handling guidance and Google’s canonical documentation both support that distinction.
Quick check: if a parameter page has search demand or real user value, treat it like a page type, not an error.
Edge Cases Where the Normal Advice Breaks Down
If you are in one of these situations, the usual “canonical everything” advice stops being good advice.
-
Pagination with valuable depth
Situation:?page=2,?page=3, and so on.
What changes: later pages may contain unique items.
What to do instead: keep the series crawlable, use self-canonicals, and make sure page 1 is not swallowing the rest. For very large archives, follow the pagination guidance from major search engine documentation rather than treating every page as a duplicate. -
Faceted navigation that creates a combinatorial explosion
Situation: hundreds of filter combinations on category pages.
What changes: crawl paths multiply faster than the value of the pages.
What to do instead: whitelist only the combinations with demand or inventory depth. Everything else should be non-linked, canonicalized, or blocked at the application layer. -
International or language parameters
Situation:?lang=,?locale=, or region parameters.
What changes: the parameter may control genuine language content.
What to do instead: use proper hreflang and stable URL structures if possible. Query-string language switching is fragile and often confuses crawl signals. -
Internal search results
Situation:?q=pages indexed from site search.
What changes: search results pages can look thin, repetitive, and endless.
What to do instead: keep them out of the index unless they are curated landing pages. Internal search is one of the worst sources of crawl waste on content-heavy sites. -
A CMS that appends random parameters
Situation: timestamps, cache-busters, or session IDs appear everywhere.
What changes: the problem is systemic, not editorial.
What to do instead: fix the CMS, template, or reverse proxy. A canonical tag alone will not rescue a system that keeps inventing URLs.
Quick check: if the parameter exists because of infrastructure rather than content, fix the system first and the SEO second.
What I Would Fix First on a Real Site
I would start with the highest-volume parameter family, then move to internal links, then the sitemap, because that order usually gives the quickest crawl improvement with the least collateral damage. If the site has utm_ clutter, session IDs, or sort parameters, those are usually the quickest wins. When Bing crawl anomalies caused by parameter URLs are the issue, that sequence matters.
Start with the templates that generate the most links. Then check the category pages that expose the most facets. After that, audit the XML sitemap and remove anything that is not meant to rank. For a large site, sample server logs for a week so you can see how often Bingbot actually hits the bad variants.
A simple priority list looks like this:
- Strip tracking parameters from internal links.
- Canonicalize or redirect duplicate parameter URLs.
- Keep only the indexable facet combinations in sitemaps.
- Validate the clean URLs in Bing Webmaster Tools.
- Re-crawl the site after the changes have had time to settle.
For a large ecommerce site, I would also compare crawl counts before and after the changes. A drop in wasted parameter crawls, plus stable impressions on the clean URLs, is the sign that the fix is working. Bing’s crawl anomaly reports and server logs should tell the same story.
If the site has one or two parameter families only, you can usually fix the problem in a day or two. If it has dozens, plan for a staged cleanup over several weeks.
Quick check: if you need a one-line answer, fix URL generation first and canonicals second.
What Bing Does and Does Not Need
Bing does not need every technically possible URL. It needs the URLs that matter, plus stable signals that tell it which version is preferred. That is why the crawl problem is usually an architecture problem, not a Bing problem.
Bing can handle some duplication. What it cannot handle gracefully is contradictory signals: indexed parameter URLs in the sitemap, internal links that keep generating them, and canonicals that point somewhere else. When that happens, crawl anomalies are predictable.
The goal is not to make the site smaller. The goal is to make it clearer. Give Bing one clean version of each content set, and it will spend less time on noise and more time on the pages that matter.
Quick check: the best fix is the one that removes ambiguity, not the one that hides it.
Drafted with AI; not yet reviewed by a person.

Related Posts
How to Tell Whether Bing Has Discovered a New Page
Bing indexing and crawl troubleshooting: The Complete Guide