How Bing Treats noindex, canonical, and robots
Last updated: October 13, 2026
Key Takeaways
- Bing can honor the strongest exclusion signal it can see.
- Yes, but not for long, if Bing can crawl the page and see the noindex clearly.
- Bing treats robots.txt as a gate, not a cleanup tool, so use it carefully.
- Each signal has a different job, and noindex usually wins over canonical when Bing can see both.
If you want one clean answer, it is this: in how Bing handles noindex, canonical, and robots directives together, Bing treats noindex, canonical tags, and robots directives as separate signals, and the most restrictive directive usually wins when they conflict. In practice, that means a page blocked from crawling may still be known to Bing, a canonical may be chosen but ignored, and a noindex can keep a URL out of results even when other signals point somewhere else.
I write about search systems for a living, and this topic matters because people often assume Bing behaves like Google in every corner case. It does not. The safest mental model is that robots.txt controls crawl access, noindex controls indexing, and canonical tags help Bing choose the preferred URL when multiple versions exist, though the exact outcome can vary.
What Bing actually does when the signals disagree
Bing tends to honor the strongest exclusion signal it can see, but only if it can see it. That distinction matters more than the tag names themselves.
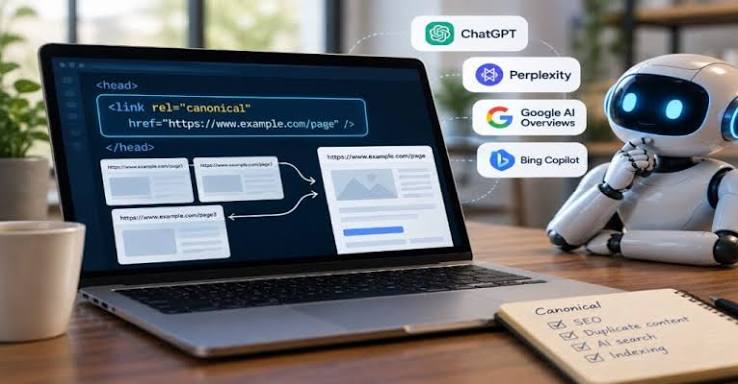
A noindex directive tells Bing not to keep a URL in its index. It can come from a meta robots tag in the HTML or from an X-Robots-Tag HTTP header. A canonical tag points Bing at the preferred version of duplicate or near-duplicate content. robots.txt can stop Bingbot from crawling a path entirely.
Here is the useful rule: if Bing cannot crawl a page because robots.txt blocks it, then it may never discover a page-level noindex or canonical tag on that URL. A blocked page can linger in the index if Bing learned about it earlier through links or sitemaps, because the crawler cannot fetch the new instructions. That is why blocking and deindexing are not the same action.
The cleanest example is a faceted category page. If /shirts?color=blue is blocked in robots.txt, Bing might still show a URL-only result if it has already indexed it. If that page now contains noindex, Bing needs access to see the instruction. If you want removal, blocking alone is usually the wrong first move. Use noindex first, let Bing recrawl it, then block only if you still need crawl control.
The key conflict rule is this: canonical is a hint, not a command. A noindex directive is stronger for removal. A robots.txt block is stronger for crawl prevention, but weaker for cleanup if the page is already indexed.
A practical source worth keeping open is Bing’s own documentation on blocking URLs and canonicalization, plus the general rules in the robots exclusion standard. The standard explains crawl control; Bing’s docs explain how its crawler applies the signals.
Can Bing index a page that is noindexed but canonicalized elsewhere?
Yes, but not for long, and not if Bing can crawl the page and see the noindex clearly.
This is the scenario that confuses people most. A page can say, “I am not indexable” with noindex, while also saying, “My preferred version is this other URL” with rel=canonical. Bing usually treats that as: do not index this page, and if the canonical is trustworthy, consolidate value toward the target URL instead.
That said, the canonical target matters. If the canonical points to a URL that is also noindex, blocked, or obviously mismatched, Bing may ignore the hint. Canonicalization works best when the target is crawlable, indexable, and closely related. A product page canonicalizing to the homepage is a classic mistake; Bing is free to discard that signal.
This is where people get the wrong lesson from generic SEO advice. They hear “canonical beats duplicate content” and apply it everywhere. Bing does not reward that habit. I would never rely on a canonical tag to fix a thin, duplicate, or parameter-heavy page if the page itself should leave the index. If the page should disappear, say so directly with noindex.
One concrete detail helps: Bing supports canonical hints in HTML and, like other major engines, can also see canonical alternatives in XML sitemaps when they are set up correctly. But a sitemap is a hint about discovery and preference, not an override for noindex. If the page itself says noindex, that instruction is more important than the sitemap’s preference.
The hard truth is that canonical and noindex solve different problems. Canonical reduces duplication. noindex removes a URL from the index. If you use both on the same page, Bing may use the canonical as a consolidation hint while still dropping the page you marked noindex. That is often fine. It is not fine if your goal is to keep that exact URL visible.
How does Bing interpret robots.txt with noindex and canonical tags?
Bing treats robots.txt as a gate, not a cleanup tool, and that is where most mistakes happen.
If Bingbot is blocked from crawling a URL, Bing cannot see page-level directives on that URL during the crawl. That includes meta robots tags and canonical tags in the HTML. The crawler can still know the URL exists from links or past crawls, but it cannot evaluate fresh on-page instructions. This is why a blocked URL can stay in search longer than expected.
There is one special case worth calling out: an X-Robots-Tag sent in the HTTP response is also unreachable if crawling is blocked. So if your plan is “block it in robots.txt and let Bing read the noindex header,” that plan fails. Bing needs access to the response to read the header.
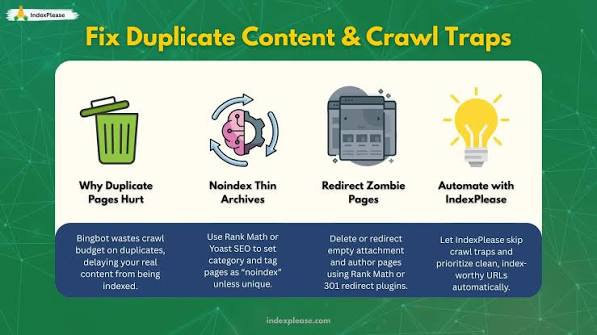
This is also why robots.txt should not be your first tool for deindexing. Use noindex when you want a page out of the index. Use robots.txt when you want to save crawl budget, prevent low-value parameter paths from being fetched, or keep search bots away from files and sections that should never be crawled.
One important exception: if a page is blocked but links to it remain on the web, Bing may still show the URL in a limited form without content snippets. That is not a sign the block is “working” the way you want. It usually means Bing knows the URL exists but cannot refresh its understanding of it.
I would summarize the practical order like this:
- If the page should not rank, use
noindex. - If the page should also stop being crawled later, remove the indexation first, then consider
robots.txt. - If the page must remain crawlable for canonical consolidation, do not block it.
For the crawler rules themselves, Bing’s webmaster documentation and the robots standard at the RFC link above are the most relevant references I trust for this topic.
Head-to-head: which signal does what, and which one wins?
The answer is that each signal has a different job, and noindex usually wins over canonical when Bing can see both.
| Criteria | noindex | canonical | robots.txt | Winner for this condition |
|---|---|---|---|---|
| Keeps page out of index | Yes, if Bing can crawl the page | No, not by itself | Not directly | noindex |
| Consolidates duplicate signals | No | Yes | No | canonical |
| Stops crawling | No | No | Yes | robots.txt |
| Lets Bing see page content | Yes | Yes | No | noindex/canonical over robots.txt |
| Works without fetching the page | No | No | Yes, for crawl blocking only | robots.txt |
| Best for parameter URLs you still want crawled | No | Sometimes | No | canonical |
| Best for pages that should disappear from results | Yes | No | No | noindex |
| Safe to combine with others | Yes | Yes | Sometimes risky | noindex |
| Can create indexing conflicts if misused | Yes, if blocked from crawl | Yes, if target is wrong | Yes, if used too early | none, if used correctly |
The winning pattern is not mysterious. Use canonical when multiple URLs should collapse into one preferred version. Use noindex when a page should not appear in search at all. Use robots.txt when the crawler should not spend time on a path, but only after you are sure you do not need Bing to read page-level instructions there.
The biggest mistake I see is using all three on the same URL without a plan. That is how a page becomes inaccessible to Bing before Bing has a chance to process the deindexing instruction. The second-biggest mistake is assuming canonical can rescue a blocked page. It usually cannot.
What should I use for duplicate pages, thin pages, and removal requests?
Use canonical for duplicates, noindex for thin or temporary pages, and robots.txt only for crawl control or private areas.
A duplicate product page with sorting parameters is the canonical case for canonical tags. Keep one clean version indexable, point the variants to it, and let Bing consolidate signals. A noindex on those parameter pages is usually too aggressive if you still want the main version discovered through them.
A thin tag archive, internal search page, or expired promo page is different. Those are usually better with noindex because you do not want them in search results at all. If the page has to stay accessible for users but not for search, noindex is the right tool.
A truly private area, like a staging directory or internal admin path, belongs in robots.txt only if you understand the limitation: blocking is not the same as secrecy. Bing cannot crawl it, but the URL may still be known if it is linked elsewhere. For actual privacy, use authentication or server-side restrictions, not robots directives.
For removals, the sequence matters. If Bing has already indexed the URL, the safest cleanup path is usually:
- add
noindex; - let Bing recrawl it;
- confirm it drops from the index;
- then decide whether
robots.txtblocking still makes sense.
If the page is gone entirely and should stay gone, serve a proper 404 or 410. That tells Bing the URL no longer belongs in the index. A 410 is often clearer for permanent removal, though the exact treatment can vary by crawler.
When would Bing’s behavior surprise you?
Bing surprises people most when crawl access and indexing status move on different timelines.
The first surprise is that a blocked URL can still appear after you block it. That happens because Bing may already know the URL from earlier crawling or inbound links. Blocking it now only prevents a fresh fetch. It does not erase historical knowledge.
The second surprise is that a canonical can be ignored if it conflicts with stronger signals or looks untrustworthy. If the canonical target returns a 302, a noindex, or unrelated content, Bing may keep the source URL or choose another representative instead. Canonicals are preference signals, not magic labels.
The third surprise is that noindex on a page blocked by robots.txt is often useless. It is not that Bing rejects the instruction; it simply cannot see it. That is a common operational mistake on sites with faceted navigation or legacy CMS rules.
Here are the situations where my recommendation flips:
- You need crawl budget more than index cleanup. Then
robots.txtmay come first, but only for URLs you do not care to deindex through crawling. - The page is a duplicate you still need crawled for consolidation. Then canonical wins over
noindex. - The page is sensitive or private. Then neither canonical nor robots directives are enough; use access control.
- The page is already blocked and still indexed. Then unblock it long enough for Bing to see
noindexor return a proper removal status.
I would be especially careful with ecommerce filters, pagination, and internal search results. Those are the places where Bing’s treatment exposes sloppy site architecture fastest.
The verdict: which directive should you choose?
Choose noindex if the page should not appear in Bing at all and Bing can crawl the page to see the instruction. Choose canonical if the page is a duplicate or near-duplicate that should fold into a preferred URL. Choose robots.txt if you want to stop crawling, but only after you know you do not need Bing to read a page-level directive there. Neither if the page is private or you need guaranteed removal without crawling.
That is the clean decision tree. It is also the one most likely to save you from self-inflicted indexing problems.
Frequently asked questions
Does Bing treat canonical as a directive?
No. Bing treats canonical as a strong hint, not a command. If the target is blocked, noindexed, or unrelated, Bing may ignore it.
Can a URL be indexed if it is blocked in robots.txt?
Yes. If Bing learned the URL earlier, it can remain in the index as a known URL even though Bingbot cannot recrawl it.
Which matters more in Bing: noindex or canonical?
noindex usually matters more for removal. Canonical is for consolidation, not exclusion.
Should I block a noindexed page in robots.txt?
Not right away. Let Bing crawl the page first so it can see the noindex. Blocking too early can prevent deindexing.
Is robots.txt enough to keep a page private?
No. It is a crawler instruction, not a security barrier. Use authentication, authorization, or server-side restrictions for privacy.
Drafted with AI; not yet reviewed by a person.

Related Posts
How to Tell Whether Bing Has Discovered a New Page
Bing indexing and crawl troubleshooting: The Complete Guide