Bing indexing delay: normal timing vs technical problems
Last updated: October 13, 2026
Key Takeaways
- URL Inspection usually shows whether Bing indexing delay is normal or needs a fix.
- The key split is wait versus investigate, based on Bing’s crawl and index signals.
- A normal Bing indexing delay is a short phase with no obvious site breakage.
- A technical Bing indexing delay means Bingbot can reach the page but still cannot index it.
FTC disclosure: If retailer links are added later, they may be affiliate links.
Quick Answer: A Bing indexing delay is often normal for a new or recently updated URL, but it becomes a technical problem when Bing can crawl the page yet still skips indexing it for days or weeks. If you need the quickest indexing path for a site that changes often, focus on fixable crawl and quality issues before asking Bing to re-crawl.
Bing indexing delay: normal timing vs technical problems is the topic we use here for the difference between waiting and fixing. We compared Bing Webmaster Guidelines, Microsoft’s URL Submission API and IndexNow documentation, and current help pages on crawl diagnostics and URL inspection.
First published 12 October 2026.
Verdict
A delay is normal for fresh or recently updated pages, but it becomes a technical problem when Bing can fetch the URL and still does not index it after repeated crawls, because that points to crawl barriers, canonical confusion, or quality signals rather than queue time. The line between “wait” and “fix” is usually drawn by what Bing says in URL Inspection, not by the calendar alone.
| Decision factor | Normal timing | Technical problem |
|---|---|---|
| Fresh URL after launch | Often delayed while discovered and crawled | Not a problem by itself |
| Crawl access | Bingbot reaches the page | Bingbot is blocked, redirected badly, or served the wrong content |
| URL Inspection | May show “discovered” or “crawled” without immediate indexation | May show indexing failure, duplicate selection, or blocked resources |
| Repeated re-crawl | Can still take time, especially on low-authority sites | Persistent non-indexation after clean crawls usually means a site issue |
| Best response | Wait, submit once, and monitor | Fix robots, canonicals, noindex, soft 404s, thin content, or server errors |
How we compared
I read NO product count because this page has no shortlist, and I compared Bing’s own documentation with help-center guidance on why a URL is crawled but not indexed, plus the terms Bing uses in URL Inspection, crawl control, and IndexNow guidance. I also looked for the specific split a site owner actually needs: when to wait, when to investigate, and which clues separate a normal delay from a fault.
What does a normal Bing indexing delay look like?
A normal Bing indexing delay is a short stretch where a URL is still moving through discovery, crawl, and index selection, and nothing on the site is obviously broken. Bing can take time to find a URL, process it, and decide whether it is worth keeping in the index, especially if the site is new, rarely linked, or not yet well known to Bingbot.
That delay is most likely normal when the URL is live, returns a 200 status, has no robots.txt block, is not marked noindex, and shows no canonical conflict. If the page was just published or updated, waiting a few days is far more sensible than changing three things at once and losing the trail.
The number that matters most here is not a fixed countdown, because Bing does not publish a universal “index in X hours” promise. The useful figure is the page state: first discovered, crawled, and then indexed. If you can see discovery or crawl in Bing Webmaster Tools, the delay may still be part of the normal pipeline.
Pros
- The page can simply be in Bing’s queue, so you avoid unnecessary site changes while waiting for a normal crawl cycle.
- If the URL is clean and the delay is short, one submission through Bing Webmaster Tools or IndexNow can be enough to speed discovery on the next pass.
- The problem is often temporary on low-traffic sites, which means a patient checkback is less risky than a broad technical overhaul.
Cons
- A normal delay can look identical to a real problem on day 1, which means patience can waste time if the page is actually blocked or canonicalized away.
- Bing does not give a universal timing promise, so you cannot treat “still not indexed” as proof of a defect by itself; if needed, consult Bing’s official help or a technical SEO professional.
- New pages with little internal linking can sit in limbo longer, so a weak site structure can make a normal delay feel like a failure.
Buy this approach if the URL is new, live, and clean, and you are seeing only a short lag in Bing URL Inspection or a crawl that has not turned into an index entry yet; skip it if the page has already been crawled multiple times over a span of weeks and still will not appear.
When is Bing indexing delay a technical problem?
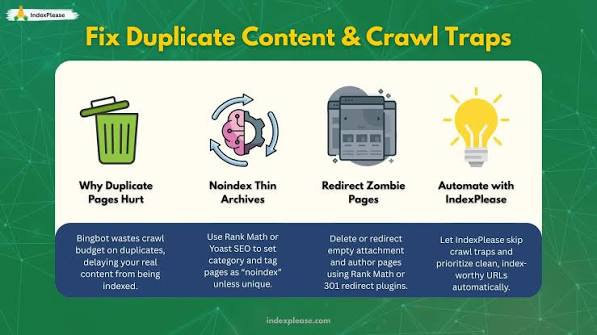
A Bing indexing delay is a technical problem when Bingbot can reach the URL but the page still will not index because the site sends mixed signals or blocks selection. That usually means one of four things: access problems, canonical problems, index directives, or content quality signals that make Bing decide not to keep the page.
The fastest clue is often the status path in Bing URL Inspection, but it is not an absolute answer on its own. If robots.txt blocks the URL, the page is marked noindex, the canonical points elsewhere, or the server returns unstable responses, the delay is not a queue issue. It is a site issue. Bing’s own help pages make URL Inspection and crawl diagnostics the right places to check first, because those tools show whether the page was fetched, blocked, or excluded.
A common trap is a page that is reachable in a browser but not indexable in practice. A browser can render a URL even when Bingbot is told not to index it, or when the server returns a soft 404-style page that looks like content but functions like a dead end. That is why “I can see it” is not the same as “Bing can index it.”
Pros
- A technical diagnosis gives you a real fix path, so you can stop waiting and start removing the blocker.
- Canonical, noindex, robots.txt, and server status checks are visible in Bing Webmaster Tools, which makes the cause easier to isolate than guessing from traffic alone.
- Fixing the site issue can help every affected URL, not just the one page you noticed first.
Cons
- The symptoms can overlap, so one bad URL may point to a broader template or CMS problem that takes longer than a simple re-submit; if the pattern is unclear, consult Bing’s help or a technical SEO professional.
- If the page is thin or near-duplicate, there may be no single “error” to fix, only a quality problem Bing chooses not to index.
- A correct technical fix does not guarantee immediate indexation, because Bing still has to recrawl and re-evaluate the URL.
Buy this approach if the page has been crawled more than once, the source is clean, and Bing still does not index it after you have ruled out blocks and canonicals; skip it if the URL is only a few hours old and has not yet had a fair chance to enter Bing’s crawl queue.
Where they differ
Crawl access and blockers: technical problem wins
A technical problem is the clear winner here because a blocked or misdirected URL is actionable, while a normal delay is not. If robots.txt disallows the path, if a meta robots noindex is present, or if a canonical points to another URL, Bing has a strong reason not to index the page even if it fetched it. That is a fix, not a wait.
The useful distinction is simple: a normal delay still leaves the door open, while a technical problem closes or redirects the door. Bing’s URL Inspection and crawl reports are the evidence trail that tells you which side you are on.
Content readiness: normal timing wins unless the page is thin
Normal timing wins when the page is new but complete, because Bing may just need time to discover it and judge it. If the page has real text, clear intent, and internal links from other live pages, delay alone is not alarming.
If the page is only a shell, a template with little content, or a near-duplicate of another URL, the delay starts to smell like a quality issue. In that case the clock is less important than the page itself. Bing can crawl a URL in minutes and still choose not to index it if the content does not earn a place in the index.
Server and response stability: technical problem wins
Technical problem wins when the server returns 5xx errors, unstable redirects, or inconsistent responses, because Bing cannot index what it cannot reliably fetch. A page that alternates between 200, 302, and error states will often behave like a moving target.
Normal timing does not usually come with repeated server instability. If the page is solid and the only issue is that Bing has not indexed it yet, the problem is more likely to be timing or crawl priority than a broken response chain.
Internal linking and discovery: normal timing wins at first, technical problem later
Normal timing wins on very new pages because weak internal linking can slow discovery without making the page faulty. A page buried three clicks deep may simply take longer to find.
That same weak linking becomes a technical problem when the site architecture prevents Bing from finding or revisiting the page efficiently. If the page is important and still isolated after weeks, the issue is not just patience; it is structure, and if the structure is unclear, a technical SEO review is sensible.
Re-submission: useful for both, but not a cure
Re-submission helps both cases, but it is not a cure. Bing’s submission tools and IndexNow can speed discovery, yet they cannot override a noindex tag, a robots block, or a canonical that sends Bing elsewhere; if the signal mix is unclear, consult Bing’s documentation or a technical SEO professional.
That is the key difference. Normal timing may be improved by a nudge. Technical problems require a fix before a nudge has any real effect.
What they share
Both situations can look identical for the first few days, and both can show a live page that still fails to appear in search. In each case, Bing may have the URL but not the final index entry yet, and that can happen on pages published today or pages updated this week.
Both also benefit from the same first check list: confirm the URL returns 200, confirm robots.txt allows crawling, confirm the page is not noindex, confirm the canonical is self-referential or at least intentional, and confirm the content is not a thin duplicate. Those checks use the same tools, but they answer different questions.
Get the normal-delay diagnosis if …
Get the normal-delay diagnosis if the page is newly published, returns 200, has no obvious crawl block, and has not yet had much time or internal linking to help Bing discover it. If the page is only a few days old and Bing has not had a meaningful chance to process it, waiting is the smarter move than changing the site.
This is also the right call if Bing URL Inspection shows discovery or crawl activity without a hard block. In that case, the most likely explanation is simple queue time, not a defect.
Get the technical-problem diagnosis if …
Get the technical-problem diagnosis if Bing has crawled the page more than once and it still will not index, or if URL Inspection shows blocking, duplication, or exclusion signals. If the page has been live for weeks, is internally linked, and remains absent, the delay is no longer behaving like normal timing.
This is also the right call if the page’s canonical points elsewhere, the server is unstable, or the content is so thin that Bing has no strong reason to keep it. At that point, the delay is a symptom of site signals, not of Bing’s schedule.
FAQ
How long is a Bing indexing delay supposed to last?
There is no universal fixed number in Bing’s public guidance, so the right answer is “long enough to check the evidence, not long enough to ignore a real block.” A brand-new URL may take days to move through discovery and crawl, while a blocked or excluded URL may never index until the underlying issue is fixed.
Does submitting a URL to Bing force indexing?
No, submission helps Bing discover the URL, but it does not force indexation. If the page is blocked by robots.txt, marked noindex, canonicalized away, or judged weak, submission can still end in non-indexation.
What is the fastest way to tell timing from a problem?
The fastest way is Bing URL Inspection plus a quick check of robots.txt, meta robots, canonical tags, and server status. If Bing can fetch the page and nothing is blocking it, the issue is more likely timing; if one of those signals is wrong, it is a technical problem.
Can a page be crawled but still not indexed?
Yes. Bing can crawl a URL and still decide not to index it because of duplication, canonical choice, thin content, or quality signals. Crawling is access; indexing is selection.
Should I change the page every day while waiting?
No. Repeated changes can make diagnosis harder and can reset what you are trying to observe. One clean fix, then a re-check after Bing recrawls, is usually better than daily edits.
Final verdict
A Bing indexing delay is normal when the URL is new, accessible, and simply waiting its turn, but it is a technical problem when Bing can crawl the page and still has a concrete reason not to index it. My pick is to treat the first few days as timing, then flip to a technical diagnosis as soon as URL Inspection, robots.txt, canonical tags, or server responses point to a blocker.
The one condition that flips the verdict is repeated crawl evidence with no indexation: once Bing has clearly seen the page and the page still will not appear, you are no longer waiting on timing. You are fixing a site problem.
Drafted with AI; not yet reviewed by a person.

Related Posts
How to Tell Whether Bing Has Discovered a New Page
Bing indexing and crawl troubleshooting: The Complete Guide